• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
AI
Report

GPT 6.1 is claimed to outscore Opus 5.5 on Energy's internal evals

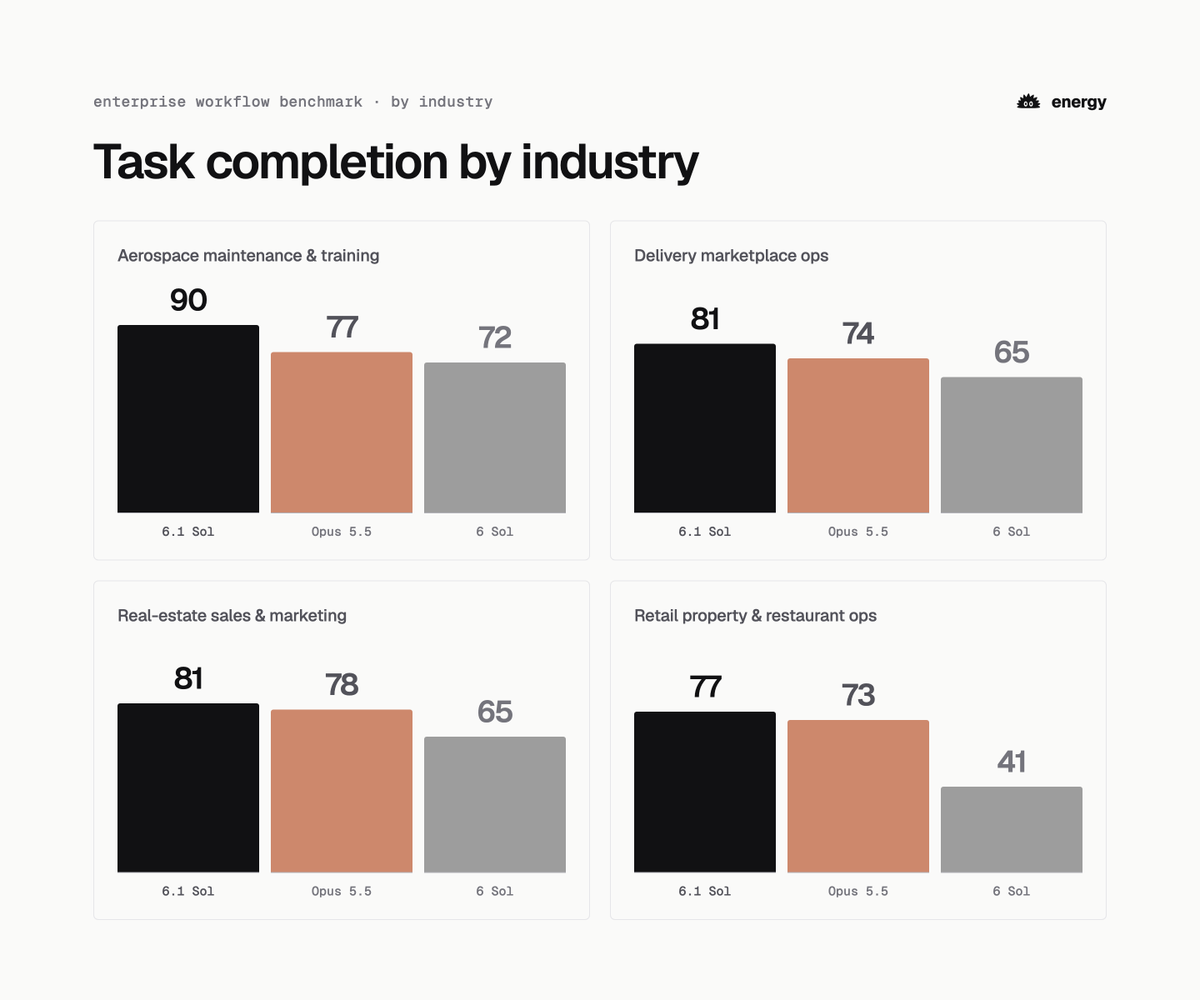
A post claims GPT 6.1 has much higher completion rates than Opus 5.5, a 40% lower price and twice the speed. The poster says GPT 6.1 is now Energy's default.

Peter WelinderPW
Yann DuboisYD
gabrielGA
8 Sources, 10d ago, first seen 10d ago

TLDR

In a September 29 post, the author says GPT 6.1 scored higher than Opus 5.5 on Energy's internal evals, which involve enterprise problems requiring business intuition and computer use. They claim much higher completion rates, a 40% lower price and twice the speed, and say GPT 6.1 is now Energy's default.

Combined views

112.6K

8 Sources, first seen 10d ago

1.2K likes51 comments179 saves93 reposts
Combined views

112.6K

8 Sources, first seen 10d ago

1.2K likes51 comments179 saves93 reposts

Sentiment

Positive58.7%41.3%Negative

Summary

Positive accounts praised GPT 6.1 Sol for its speed, efficiency, and real-world task completion over Opus 5.5, while negative replies questioned the claims' objectivity and noted weaker design taste plus accessibility concerns.

Based on 20 sentiment-bearing replies from 20 accounts across 3 conversations.

Featured Source

Sentiment

Positive58.7%41.3%Negative

Summary

Positive accounts praised GPT 6.1 Sol for its speed, efficiency, and real-world task completion over Opus 5.5, while negative replies questioned the claims' objectivity and noted weaker design taste plus accessibility concerns.

Based on 20 sentiment-bearing replies from 20 accounts across 3 conversations.

Related

River API is pitched as a cheap route to task-specific open models

Igor Babuschkin claims fine-tuned open-weight models can beat GPT-6 Astra and Claude Opus 5.5 for under 1% of the cost.

Grok Bot reportedly shifting to a best-model router, with Claude Opus 5.5, MidJourney and Suno in the mix

Elon Musk said Grok Bot will use “the best back end model for any given task,” naming Claude Opus 5.5, MidJourney, Suno and other APIs in a future-facing plan rather than a confirmed live rollout.

Claude Opus 5.5 reportedly scores 94.2% on NerfBench, within normal variance

BridgeMind AI says Opus 5.5 was scoring above its launch level a day earlier but cautions that the dip is not yet evidence of a nerf.

8 Sources

emil@emilahlbackIn our internal knowledge work evals, GPT 6.1 Sol is the best model we've tested. It completed more of the work independently than Claude Opus 5.5, at 40% of the cost and nearly twice the speed, and led in every industry we measured.10d
gabriel@gabriel1GPT 6.1 scores significantly higher than Opus 5.5 on Energy's internal evals: - Much higher completion rates - 40% less price - 2x the speed These are real enterprise problems that require business intuition and computer use, just like a real person GPT 6.1 is now our default10d
Peter Welinder@npewGPT 6.1 Sol is great for real world task. The best.10d
Ted Sanders@sanderstedRT @emilahlback: In our internal knowledge work evals, GPT 6.1 Sol is the best model we've tested. It completed more of the work independe…10d
Yann Dubois@yanndubsRT @gabriel1: GPT 6.1 scores significantly higher than Opus 5.5 on Energy's internal evals: - Much higher completion rates - 40% less price…10d
Peter J. Liu@peterjliuGPT 6.1 Sol on an internal benchmark absolutely mogs Claude in efficiency at the same quality. It's counter-intuitive but larger models can be more efficient than smaller models for hard tasks.9d
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    Claude Opus 5.5

    8 Sources

    emil@emilahlbackIn our internal knowledge work evals, GPT 6.1 Sol is the best model we've tested. It completed more of the work independently than Claude Opus 5.5, at 40% of the cost and nearly twice the speed, and led in every industry we measured.10d
    gabriel@gabriel1GPT 6.1 scores significantly higher than Opus 5.5 on Energy's internal evals: - Much higher completion rates - 40% less price - 2x the speed These are real enterprise problems that require business intuition and computer use, just like a real person GPT 6.1 is now our default10d
    Peter Welinder@npewGPT 6.1 Sol is great for real world task. The best.10d
    Ted Sanders@sanderstedRT @emilahlback: In our internal knowledge work evals, GPT 6.1 Sol is the best model we've tested. It completed more of the work independe…10d
    Yann Dubois@yanndubsRT @gabriel1: GPT 6.1 scores significantly higher than Opus 5.5 on Energy's internal evals: - Much higher completion rates - 40% less price…10d
    Peter J. Liu@peterjliuGPT 6.1 Sol on an internal benchmark absolutely mogs Claude in efficiency at the same quality. It's counter-intuitive but larger models can be more efficient than smaller models for hard tasks.9d
    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet