• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
AI
Report

Sonnet 5.5’s claimed strength comes with questions about cost and token use

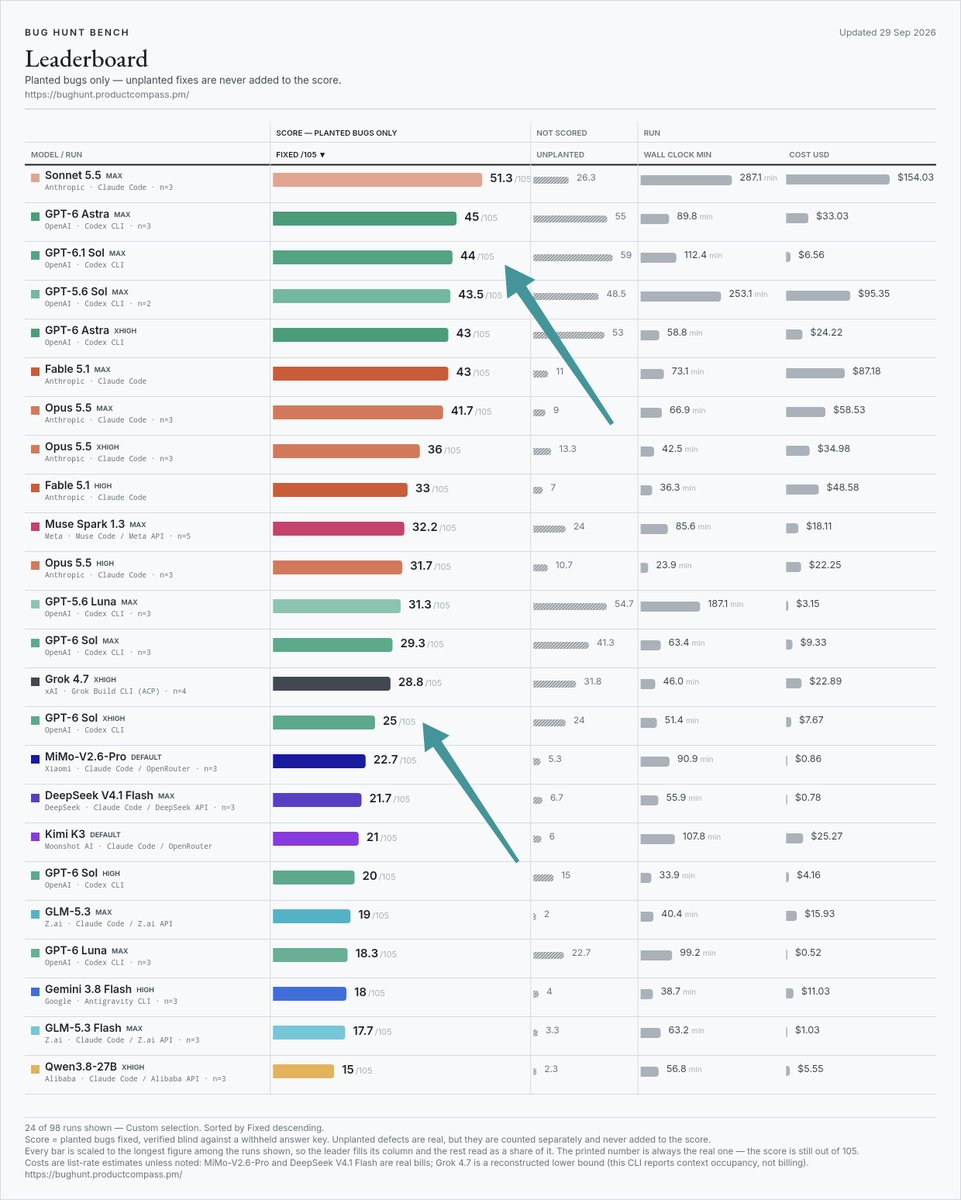
A user says Sonnet 5.5 is far stronger, but asks whether that comes at 23 times the cost and more than 10 times the tokens. They suggest testing Astra-series models in teams.

Peter WelinderPW
Teortaxes▶️ (DeepSeek 推特🐋铁粉 2023 – ∞)T(
Andrew CurranAC
5 Sources, 10d ago, first seen 10d ago

TLDR

A user calls Sonnet 5.5 “stronger, by far,” while questioning whether it comes at 23 times the cost and over 10 times the tokens. They speculate that Astra-series models work like “native swarm intelligence” and may be better tested in teams than with more serial effort.

Combined views

361.8K

5 Sources, first seen 10d ago

3.3K likes238 comments825 saves285 reposts
Combined views

361.8K

5 Sources, first seen 10d ago

3.3K likes238 comments825 saves285 reposts

Sentiment

Positive75.6%24.4%Negative

Summary

Many accounts praised GPT-6.1 Sol's strong coding performance and token efficiency on real repositories and bug fixes, while others criticized recent usage plan cuts and API pricing changes.

Based on 85 sentiment-bearing replies from 82 accounts across 3 conversations.

Featured Source

Sentiment

Positive75.6%24.4%Negative

Summary

Many accounts praised GPT-6.1 Sol's strong coding performance and token efficiency on real repositories and bug fixes, while others criticized recent usage plan cuts and API pricing changes.

Based on 85 sentiment-bearing replies from 82 accounts across 3 conversations.

Related

River API is pitched as a cheap route to task-specific open models

Igor Babuschkin claims fine-tuned open-weight models can beat GPT-6 Astra and Claude Opus 5.5 for under 1% of the cost.

Grok Bot reportedly shifting to a best-model router, with Claude Opus 5.5, MidJourney and Suno in the mix

Elon Musk said Grok Bot will use “the best back end model for any given task,” naming Claude Opus 5.5, MidJourney, Suno and other APIs in a future-facing plan rather than a confirmed live rollout.

Claude Opus 5.5 reportedly scores 94.2% on NerfBench, within normal variance

BridgeMind AI says Opus 5.5 was scoring above its launch level a day earlier but cautions that the dip is not yet evidence of a nerf.

5 Sources

Paweł Huryn@PawelHurynSo I tested GPT-6.1 Sol on real work: 2 repos, 105 planted bugs. Find and fix what you can. Unlike GPT-6 Sol, which was just a nerfed GPT-5.6 Terra, this one is real. The results: - GPT-6 Astra (max): 45 for $33 - GPT-6.1 Sol (max): 44 for $6.56 - GPT-5.6 Sol (max): 43.5 for $95.35 - Opus 5.5 (max): 41.7 for $58.53 - GPT-6 Sol (max): 29.3 for $9.33 With a model like this, the 50% cut to the $200 plan doesn't matter. n=1. More runs and results at more effort levels dropping in this thread over the next few hours 🧵10d
Teortaxes▶️ (DeepSeek 推特🐋铁粉 2023 – ∞)@teortaxesTexYes, Sonnet 5.5 is still stronger, by far but unironically: AT WHAT COST? 23 times more?! So, >10x more tokens? pretty bonkers outcome I guess Astra-series are native swarm intelligence which is why serial-effort juice doesn't add enough oomph. You need to test them in teams.10d
Andrew Curran@AndrewCurran_@teortaxesTex Yes, they continually improve these last few months.10d
Peter Welinder@npewRT @PawelHuryn: So I tested GPT-6.1 Sol on real work: 2 repos, 105 planted bugs. Find and fix what you can. Unlike GPT-6 Sol, which was ju…10d
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    Sonnet 5.5GPT-6.1 SolClaude Opus 5.5
    GPT-6 Astra

    5 Sources

    Paweł Huryn@PawelHurynSo I tested GPT-6.1 Sol on real work: 2 repos, 105 planted bugs. Find and fix what you can. Unlike GPT-6 Sol, which was just a nerfed GPT-5.6 Terra, this one is real. The results: - GPT-6 Astra (max): 45 for $33 - GPT-6.1 Sol (max): 44 for $6.56 - GPT-5.6 Sol (max): 43.5 for $95.35 - Opus 5.5 (max): 41.7 for $58.53 - GPT-6 Sol (max): 29.3 for $9.33 With a model like this, the 50% cut to the $200 plan doesn't matter. n=1. More runs and results at more effort levels dropping in this thread over the next few hours 🧵10d
    Teortaxes▶️ (DeepSeek 推特🐋铁粉 2023 – ∞)@teortaxesTexYes, Sonnet 5.5 is still stronger, by far but unironically: AT WHAT COST? 23 times more?! So, >10x more tokens? pretty bonkers outcome I guess Astra-series are native swarm intelligence which is why serial-effort juice doesn't add enough oomph. You need to test them in teams.10d
    Andrew Curran@AndrewCurran_@teortaxesTex Yes, they continually improve these last few months.10d
    Peter Welinder@npewRT @PawelHuryn: So I tested GPT-6.1 Sol on real work: 2 repos, 105 planted bugs. Find and fix what you can. Unlike GPT-6 Sol, which was ju…10d
    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet