• Home
  • Technology
  • Gaming
  • Entertainment
  • World & Business
  • Science
  • Sports
  • AI
HomeTechnologyGamingEntertainmentWorld & BusinessScienceSportsAI
AI
Announcement

AI web text reportedly helped only data-starved models in COLM 2026 study

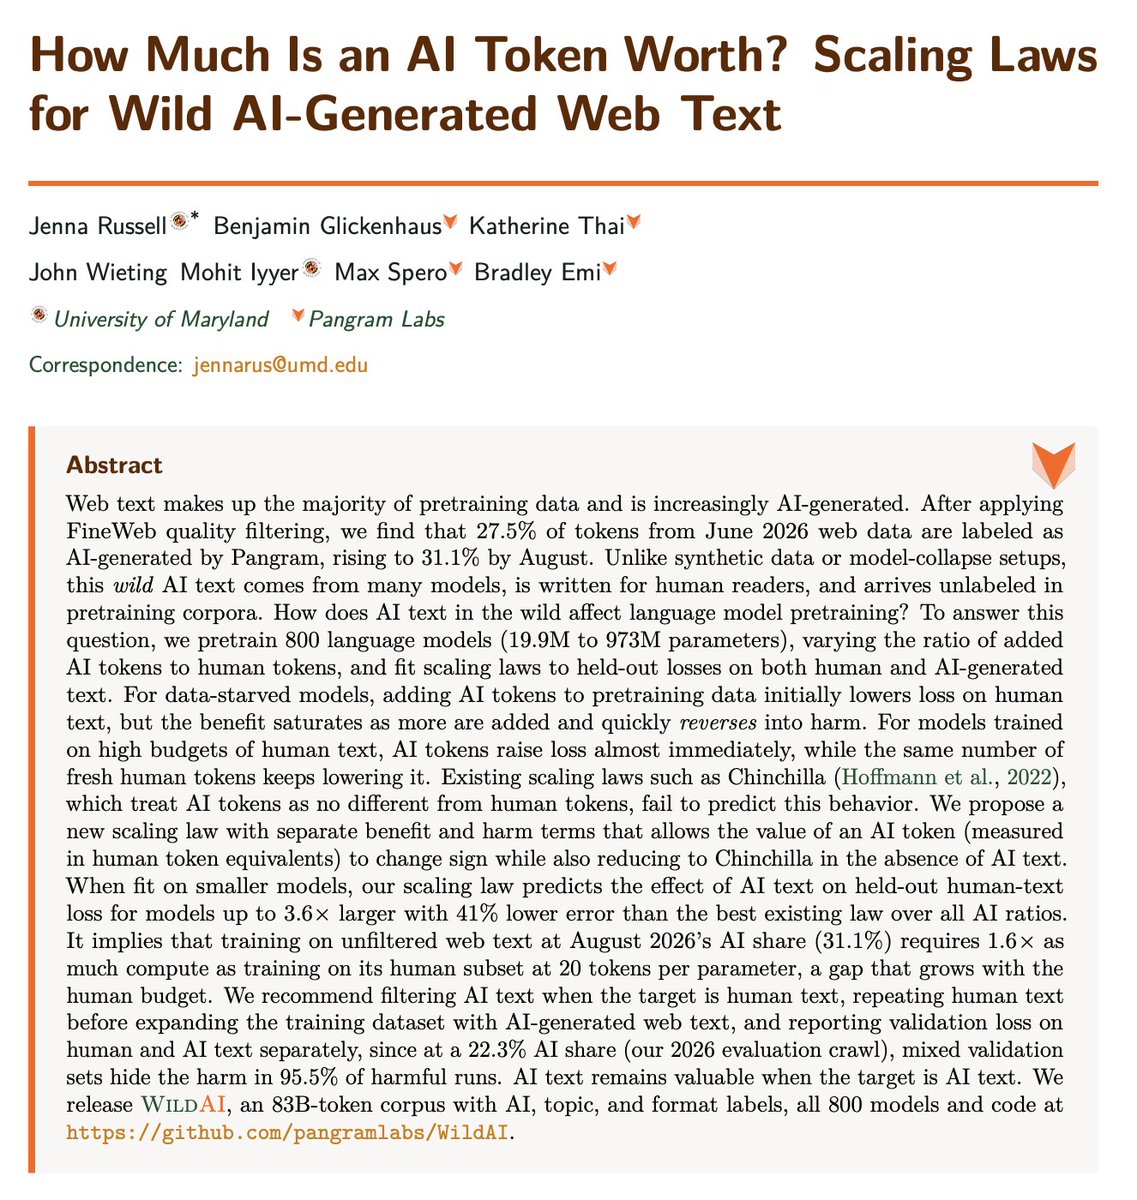
In X posts, Jenna Russell said Pangram labeled 31% of FineWeb-filtered web tokens as AI-generated in August 2026, up from 10% in June 2024. She said a study of 800 language models found AI tokens lowered loss on human text for data-starved models under about 10 human tokens per parameter, but raised it almost from Ch

Yoav ArtziYA
Mohit IyyerMI
Siva ReddySR
12 Sources, 10d ago, first seen 10d ago

TLDR

In X posts, Jenna Russell said Pangram labeled 31% of FineWeb-filtered web tokens as AI-generated in August 2026, up from 10% in June 2024. She said a study pretraining 800 language models found AI tokens lowered loss on human text only for data-starved models under about 10 human tokens per parameter, then raised it almost immediately from Chinchilla-optimal settings onward. Mohit Iyyer’s no-new-data comparison was his own summary.

Combined views

13.9K

12 Sources, first seen 10d ago

222 likes22 comments57 saves87 reposts

Combined views

13.9K

12 Sources, first seen 10d ago

222 likes22 comments57 saves87 reposts

Jenna Russell said in an X thread that Pangram labeled 31% of FineWeb-filtered web tokens as AI-generated in August 2026, up from 10% in June 2024.

Featured Source

In the same post, Russell said her team pretrained 800 language models ranging from 19.9 million to 973 million parameters on mixes of human and AI web text to measure what those mixes do to pretraining.

In a follow-up post, Russell said that for data-starved models "under ~10 human tokens per param," adding AI tokens lowered loss on human text.

She said the pattern changed from "Chinchilla-optimal (20) on": adding AI tokens raised loss on human text almost immediately, while adding human tokens continued to lower the loss.

Mohit Iyyer later offered his own summary of the work on X, writing that across most standard training budgets, adding AI text makes models worse than if no new training data were added at all.

That no-new-data comparison was Iyyer's summary of the work, not Russell's wording in the cited posts.

Sentiment

Positive——Negative

Summary

Not enough discussion yet.

No sentiment analysis available yet.

Sentiment

Positive——Negative

Summary

Not enough discussion yet.

No sentiment analysis available yet.

Related

Narrative choices alone may give away AI-written fiction

A presenter of StoryScope says their work finds that narrative choices can give away AI fiction without relying on stylistic cues such as word choice or sentence structure.

AI Models Struggle to Generate Humanized Text

Academics test Codex and Claude for evading AI text detectors.

12 Sources

Jenna Russell@jennajrussellHow much is an AI token worth? We fit scaling laws to find out! In August 2026, Pangram labels 31% of FineWeb-filtered web tokens as AI-generated, up from 10% in June 2024. We pretrained 800 LMs (19.9M–973M params) on mixes of human and AI web text to measure what it does to pretraining 🧵10d
Xinyue Liu @ COLM 2026@irisiris_lsuper cool work 🎉10d
Mohit Iyyer@MohitIyyerTurns out that it's not just humans whose brains melt when reading AI slop: we pretrain hundreds of models with different mixes of human-written and AI-generated web text, and we find that across most standard training budgets, adding AI text makes models worse than if we added no new training data at all. This is increasingly pressing since almost a third of FineWeb-filtered web text is AI-generated as of last month, and this number is rising fast!10d
Yoav Artzi@yoavartzi@MohitIyyer Mode collapse?10d
Bhuwan Dhingra@bhuwandhingraRT @jennajrussell: How much is an AI token worth? We fit scaling laws to find out! In August 2026, Pangram labels 31% of FineWeb-filtered…10d
Tu Vu@tuvllmsRT @jennajrussell: How much is an AI token worth? We fit scaling laws to find out! In August 2026, Pangram labels 31% of FineWeb-filtered…10d
Tuhin Chakrabarty@TuhinChakr@bhuwandhingra @jennajrussell Great question Bhuwan!! I think for post training where we can do RLVR its fine? But for non verifiable tasks if synthetic data is used it invariably leads to even more slop ( very AI sounding text). RL does amplify pre training behavior10d
Siva Reddy@sivareddygRT @MohitIyyer: Turns out that it's not just humans whose brains melt when reading AI slop: we pretrain hundreds of models with different m…9d
Lucy Li@lucy3_liRT @jennajrussell: How much is an AI token worth? We fit scaling laws to find out! In August 2026, Pangram labels 31% of FineWeb-filtered…9d
    • Home
    • Technology
    • Gaming
    • Entertainment
    • World & Business
    • Science
    • Sports
    • AI
    Jenna RussellPangram

    12 Sources

    Jenna Russell@jennajrussellHow much is an AI token worth? We fit scaling laws to find out! In August 2026, Pangram labels 31% of FineWeb-filtered web tokens as AI-generated, up from 10% in June 2024. We pretrained 800 LMs (19.9M–973M params) on mixes of human and AI web text to measure what it does to pretraining 🧵10d
    Xinyue Liu @ COLM 2026@irisiris_lsuper cool work 🎉10d
    Mohit Iyyer@MohitIyyerTurns out that it's not just humans whose brains melt when reading AI slop: we pretrain hundreds of models with different mixes of human-written and AI-generated web text, and we find that across most standard training budgets, adding AI text makes models worse than if we added no new training data at all. This is increasingly pressing since almost a third of FineWeb-filtered web text is AI-generated as of last month, and this number is rising fast!10d
    Yoav Artzi@yoavartzi@MohitIyyer Mode collapse?10d
    Bhuwan Dhingra@bhuwandhingraRT @jennajrussell: How much is an AI token worth? We fit scaling laws to find out! In August 2026, Pangram labels 31% of FineWeb-filtered…10d
    Tu Vu@tuvllmsRT @jennajrussell: How much is an AI token worth? We fit scaling laws to find out! In August 2026, Pangram labels 31% of FineWeb-filtered…10d
    Tuhin Chakrabarty@TuhinChakr@bhuwandhingra @jennajrussell Great question Bhuwan!! I think for post training where we can do RLVR its fine? But for non verifiable tasks if synthetic data is used it invariably leads to even more slop ( very AI sounding text). RL does amplify pre training behavior10d
    Siva Reddy@sivareddygRT @MohitIyyer: Turns out that it's not just humans whose brains melt when reading AI slop: we pretrain hundreds of models with different m…9d
    Lucy Li@lucy3_liRT @jennajrussell: How much is an AI token worth? We fit scaling laws to find out! In August 2026, Pangram labels 31% of FineWeb-filtered…9d
    Today's Rank

    —

    Not ranked yet

    Today's Rank

    —

    Not ranked yet